Daniel Garcia
Local AI: when does it make sense to run a model on your own computer?
Versão portuguesa →Running an AI model on our own computer sounds appealing. But available memory, response speed and the quality of the results all affect the choices we make. Before reaching for a larger model, it is worth working out which one is sufficient for the task we want to complete.
In this article
There is something appealing about the idea of having an artificial intelligence model running on our own computer.
There is no API to configure, we do not need to send everything to an external service and, in theory, once the model has been downloaded we can use it without counting requests, tokens or usage costs.
That curiosity is exactly what led me to try local AI. Installing Ollama is relatively straightforward, downloading a model is hardly a secret ritual either, and within a few minutes we can be asking questions to a model that is genuinely running on our own machine.
So far, so good.
The problem appears when we ask the next question:
Now that I can run a model locally, can I actually work with it?
And at this point the answer stops being a simple “yes” or “no”.
It depends on the model, the task, the hardware and, above all, what we expect to get from it.
Local AI does not necessarily mean thousands of euros in hardware
When we talk about local artificial intelligence, there is a tendency to immediately imagine a workstation with a huge graphics card, dozens of gigabytes of memory and a power supply capable of heating a small room in winter.
It does not have to be like that.
Today there are relatively small models that can run on perfectly ordinary computers and are fast enough for small tasks.
We can use them to:
- classify text;
- extract specific information;
- perform small transformations;
- summarise short content;
- generate structured responses;
- run simple automations;
- assist with small programming tasks;
- work with information we prefer to keep local.
That is already a real use of AI.
A model does not need to write an entire application or analyse hundreds of pages to be useful.
In the current Gemma family documentation, for example, Google positions 270-million and 1-billion-parameter models for mobile devices and single-board computers, 4B models for desktops and small servers, and larger variants for progressively more demanding hardware.
In other words, there is a whole spectrum between “this model fits on my computer” and “I need a small power station”.
The first test is almost always fun
With tools such as Ollama, the initial experience is fairly simple.
We install the tool, choose a model and run something like:
ollama run model-nameA moment later we have a prompt in front of us and naturally begin with the classics:
Explain this.
Summarise that.
Write a function to do whatever I need.
And it works.
That is when we start thinking that perhaps we can replace half the cloud services we use.
Then we download a larger model.
And another.
And we start to realise that the number of parameters is not just a detail written on the download page.
Small models: fast, lightweight and genuinely useful
One of the most interesting aspects of recent AI development is the increasing capability of small models.
A model with only a few billion parameters can now solve tasks that, not long ago, we associated with significantly larger models.
Microsoft demonstrated this quite clearly with the Phi family. Phi-4-mini, with 3.8 billion parameters, was designed precisely to provide substantial capability in a compact model and, according to its technical report, can in some tasks approach or outperform considerably larger models.
That does not mean a 3B or 4B model is equivalent to the best models available in the cloud.
It is not.
It means that there are already many tasks for which we simply do not need the largest model available.
If I want to classify messages, extract fields from text, convert a short description into a JSON structure or help a local automation make a limited decision, a small model may be exactly the right tool.
And in that scenario, local AI starts to make a lot of sense.
Then we raise our ambitions
The problem usually starts when we stop asking for small tasks and move on to more demanding work.
We want to:
- analyse long documents;
- work with large contexts;
- generate substantial amounts of code;
- understand complex projects;
- perform deeper reasoning;
- compare large amounts of information;
- maintain long conversations;
- obtain responses close in quality to the best cloud services.
That is when we start to feel the weight of the model.
Literally.
A larger model takes up more disk space, needs more memory and requires greater processing capacity. If a significant part of the model does not fit in GPU memory, some of the workload may have to move through system memory and the CPU, usually with a noticeable impact on speed.
The model may still run.
But there is an important difference between running and being pleasant to use every day.
Waiting several seconds for a short answer may still be perfectly acceptable. Waiting a long time for every iteration while programming, reviewing documentation or experimenting with prompts changes the experience completely.
That is when I realised that “running” is not enough
In my own tests with Ollama, I tried models of very different sizes.
The smaller models quickly showed one advantage: for well-defined tasks, they respond quickly and the computer remains perfectly usable.
When we move to much larger models, the potential quality improves, but so does the computational cost.
In my case, it was possible to run larger models on fairly modest hardware by current AI standards. That in itself is interesting.
But it also became clear that being able to load a model and get an answer does not necessarily mean we have a productive tool.
If every important interaction means waiting too long, we end up returning to the cloud for many tasks.
And that led me to what I think is the genuinely important question:
What is the smallest model capable of solving my problem well?
That question is far more useful than:
What is the largest model I can install?
Memory has become part of the conversation
When we think about building a computer for local AI, we quickly end up talking about RAM and VRAM.
And recent times have not been particularly kind to anyone looking to buy memory.
Strong demand associated with servers and artificial intelligence infrastructure has put pressure on supply. During 2026, TrendForce reported very significant increases in DRAM and NAND contract prices and continued to point to a tight market throughout the year.
Graphics memory has not been isolated from this problem either, because manufacturers have limited production capacity and there is enormous demand for components intended for AI infrastructure.
This creates an interesting situation.
On the one hand, we want more RAM and more VRAM to run larger models.
On the other hand, that hardware has become more expensive precisely because of the growth of artificial intelligence itself.
AI is, in a way, making the hardware we need to run AI more expensive.
There is a certain irony in that.
But the models are evolving too
Fortunately, progress is not happening only on the hardware side.
Models are becoming more efficient as well.
Techniques such as quantisation allow model weights to be represented with fewer bits, significantly reducing the memory required.
A 2026 study on Small Language Model efficiency found, in the tested scenario, an approximately 71% reduction in peak memory consumption and an 83% increase in throughput when applying 4-bit quantisation to Phi-3-mini, with relatively small degradation across several tests.
The exact figures vary between models, hardware and techniques, but the principle matters:
We can substantially reduce a model’s requirements without losing a proportional amount of usefulness.
Manufacturers themselves are increasingly designing models with local execution in mind.
Google provides Gemma variants explicitly aimed at mobile devices, laptops, desktops and small servers. Tools such as Ollama also continue to improve inference engines and support for quantised formats.
So while hardware has become more expensive, software is learning to make better use of what we already have.
A small model is not a useless model
There is another idea that I think is worth challenging.
Sometimes we judge local models using the same question we use for the largest cloud models:
Can it do everything?
Probably not.
But perhaps that is the wrong question.
A DNS server does not edit video either, and nobody considers that a particularly worrying limitation.
A tool should be judged by the task it was chosen to perform.
A small model can be excellent for an internal automation that receives a message and chooses between five categories.
It may be sufficient to turn text into a structure.
It may answer questions about a small collection of documentation.
It may process confidential information that we do not want to send to external services.
It may work without Internet access.
It may integrate with a local application without variable per-call costs.
In that type of use, the goal is not to compete with the largest model available.
It is to solve a specific problem well.
When local AI makes sense
After trying different models and understanding the limitations better, there are several scenarios where I can clearly see the advantages of local use.
Privacy
The data does not need to leave the machine or infrastructure we control.
This can matter when we work with:
- internal documents;
- business information;
- customer data;
- proprietary code;
- content that we simply do not want to send to third parties.
This does not eliminate the need for security. It simply changes where the data is processed.
Offline operation
Once the model has been downloaded, many solutions can work without Internet access.
For certain internal tools or isolated environments, this can be very useful.
Small, frequent automations
If we have a well-defined task that runs frequently, a local model can avoid constant API calls.
A small model can be particularly interesting here.
Experimentation and learning
There is also an advantage that does not show up on a spreadsheet.
Running models locally helps us understand better how all of this works.
We start paying attention to parameters, quantisation, context, memory, CPU, GPU and throughput.
We stop seeing AI as just a text box in a browser.
Infrastructure control
We can choose the model, the version, the limits and when we want to update it.
For certain projects, that predictability can be more important than constantly using the latest model.
When it probably does not make sense
There are also situations where local AI may simply be a complicated way of solving a problem that was already solved.
We regularly need the most capable models
If the work requires complex reasoning, huge contexts, advanced code generation or intensive analysis, a cloud service may provide far more capability without us having to buy and maintain the infrastructure.
We want speed with large models
A large model may run locally, but to be genuinely fast it can require a substantial amount of VRAM and high-end hardware.
It is possible.
The question is whether it makes economic sense.
We use AI only occasionally
Investing thousands of euros in hardware to run something locally that we use only a few times a week may not be a great financial decision.
An API is paid for only when it is used.
An expensive GPU is still expensive when it is switched off.
We do not want to manage another infrastructure
Drivers, versions, models, disk space, updates, compatibility and monitoring also have a cost.
It may not show up directly on the electricity bill, but it shows up in our time.
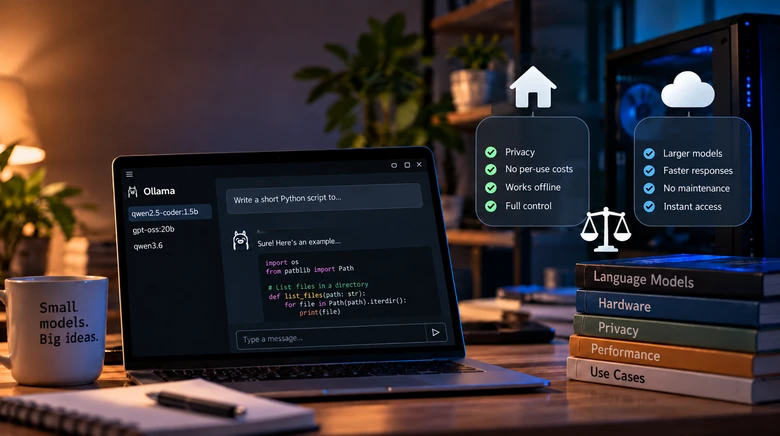
Local or cloud? Perhaps the answer is “both”
For a while, the discussion around local AI seemed to follow the usual technology logic:
Which one is better?
But perhaps there is no need to choose a side.
We can use local models for:
- simple tasks;
- sensitive information;
- automations;
- classification;
- offline processing;
- experiments.
And use the cloud when we need:
- much larger models;
- advanced reasoning;
- extensive context windows;
- high speed;
- specialised capabilities.
A hybrid architecture allows us to choose the tool based on the task.
And technically, that seems far more interesting to me than trying to force a single model to do everything.
What about two or three years from now?
Here we inevitably move into the realm of prediction.
We cannot claim that in two years any cheap computer will run models equivalent to today’s best cloud systems.
But there is a trend that seems difficult to ignore.
Small models are becoming more capable.
Quantisation is improving.
Architectures are becoming more efficient.
Inference engines are making better use of hardware.
And manufacturers themselves are designing models specifically for execution on personal computers and mobile devices.
This means the boundary is moving.
What requires a very expensive workstation today may not require the same investment in the future.
And what we consider a “small model” today may offer capabilities that we currently associate with much larger models.
That is why I think it is entirely plausible that, in the short to medium term, local models will become capable enough for a much larger share of everyday work without necessarily requiring thousands of euros in hardware investment.
Interestingly, this may happen while RAM and graphics cards remain expensive.
The right question is not “what is the largest model?”
After these experiments, my view of local AI became considerably more pragmatic.
It is entirely possible to run a local model quickly without extraordinary hardware.
For small tasks, it can be a simple, private, economical and highly effective solution.
It is also possible to run large models locally.
But when we want to combine high capability, large context and fast responses, the hardware investment rises substantially and stops being viable for many people.
This is where we need to separate technical possibility from practical decision-making.
Just because we can do something does not mean it is the best way to do it.
And perhaps the future of local AI is not about having the largest possible model at home.
Perhaps it is exactly the opposite:
having the smallest model capable of solving our problem well.
If that boundary continues to move at its current pace, what is today an interesting experiment for people who enjoy tinkering with technology may become, sooner than we expect, a perfectly normal way of working every day.
Notes
Parameters
Internal values learned during model training. In simplified terms, models with more parameters tend to have greater capacity, but they also require more resources. Parameter count alone does not determine quality.
VRAM — Video Random Access Memory
Memory available on the graphics card. In local inference, it is often one of the main factors limiting the size of the model we can run directly on the GPU.
Quantisation
A technique that reduces the precision used to represent a model’s weights, allowing the model to occupy less space and require less memory to run. There is usually some trade-off between efficiency and quality.
Throughput
The amount of work processed per unit of time. In language models it is often measured in tokens per second.
Inference
The stage in which an already-trained model receives an input and produces a response. This is what happens when we ask a local model a question.
Supporting documentation and sources
- Google AI for Developers: Gemma models and recommended platforms
- Google AI for Developers: Gemma overview and quantised models
- Microsoft Research: Phi-4-Mini Technical Report
- Microsoft Research: Phi-3 Technical Report
- Ollama: performance and quantisation improvements
- Strategies for computational efficiency in small language models
- TrendForce: memory market in Q4 2026
- TrendForce: impact of AI server demand on memory prices